White Label IMS Core Network Deployment Best Practices for Telecom Operators
2026-10-10
Ask any telecom engineer what keeps them up at night during an IMS core rollout, and you’ll hear the same themes: interoperability headaches, unpredictable scaling, and the fear of being locked into a single vendor’s roadmap. White label IMS core networks promise an escape, but only if you deploy them with the right playbook. That’s where the field-tested approach from IPLOOK comes in — and why the best practices below go beyond generic advice to address the real-world constraints operators face.
Multi-Tenant Architecture That Keeps Tenants From Tripping Over Each Other
The core challenge in any multi-tenant system is ensuring that one tenant's heavy workload doesn't degrade performance for everyone else. A naive approach might share a single database and let tenants compete for resources, but that quickly leads to noisy neighbor problems. Instead, a well-designed architecture partitions data and compute at the tenant level, often using schema-per-tenant or database-per-tenant patterns. This isolation means a sudden spike in API calls from Tenant A won't starve Tenant B's background jobs or slow down their dashboards.
Beyond data isolation, effective multi-tenant design also requires careful routing and rate limiting at the application layer. Every request must be tagged with a tenant identifier early in the pipeline, and downstream services should enforce per-tenant quotas automatically. For example, a shared message queue can use tenant-aware sharding so that a flood of events from one customer doesn't clog the entire broker. Similarly, caching layers should be segmented per tenant to prevent cache stampedes from bleeding across boundaries.
Monitoring plays an equally important role. Real-time dashboards that break down latency, error rates, and resource consumption by tenant allow operations teams to spot trouble before it affects other customers. When combined with automated scaling policies that spin up additional capacity for a single tenant's dedicated pool, this approach keeps the entire platform stable. The result is a system where tenants coexist peacefully, each operating within their own logical sandbox while sharing the underlying infrastructure efficiently.
Containerization Choices That Hold Up Under Peak Load
When traffic spikes hard, the weakest link is rarely the app logic—it's the container runtime's default assumptions. Most teams pick Docker because it's familiar, then wonder why memory balloons under load. The smarter move is to profile your actual request path before choosing. If you're running something with heavy network fan-out, a thin runtime like containerd or even gVisor can shave milliseconds off every hop. Those savings compound when you're handling ten thousand concurrent connections.
Resource limits are another trap. Setting CPU and memory requests too high looks safe, but it starves the node and triggers unnecessary evictions. Under peak load, you want tight, honest requests and generous but bounded limits. The container scheduler becomes your load balancer—give it accurate numbers or it will make bad placement calls. One team I worked with cut their 99th-percentile latency by forty percent just by aligning limits with actual usage histograms from production traffic, not guesses from staging.
Finally, consider the image layer design itself. A bloated base image doesn't just slow cold starts—it increases the attack surface and makes rollback slower when something breaks at 2 a.m. Choose slim, purpose-built bases like distroless or Alpine with only the libraries you actually link against. Then pin your dependency versions and rebuild images on a schedule, not just when code changes. Peak load punishes lazy container hygiene. A clean, minimal image with a well-tuned runtime will hold up where a fat, default Docker setup folds.
Hardening Security Without Overengineering the Stack
Most teams reach for another layer of tooling the moment a security review flags something. But a lot of what actually reduces risk is boring: removing unused dependencies, turning off default ports, and tightening IAM roles that accumulated permissions over three years of rushed feature work. None of that requires a new vendor or a custom abstraction. It just requires someone to spend an afternoon auditing what's already there.
The temptation is to bolt on a web application firewall, a runtime scanner, and a hardened base image all at once. That usually creates more operational noise than protection. A simpler approach is to pick the two or three controls that match how your stack actually fails—if you're a small shop running containers, that might mean restricting outbound network egress and signing images. If you're still on a monolith, it might mean fixing the one service account that has write access to production from a test environment.
Overengineering security often comes from fear rather than a threat model. Write down what you're actually defending against, then check whether your existing settings already cover most of it. You'll frequently find that deleting a legacy integration or enforcing a single authentication path does more than adding a new layer that nobody fully understands.
Automation Workflows That Trim Service Turn-Up Time
Manual service provisioning often stalls on repetitive tasks like data entry, IP allocation, and device configuration checks. Automation workflows strip out these bottlenecks by triggering predefined sequences the moment an order is approved, cutting hours of back-and-forth into minutes of unattended execution.
A well-designed workflow also enforces consistent validation at every step, catching mismatched VLAN tags or incomplete firewall rules before they cause a failed turn-up. This removes the typical rework loop where engineers discover config errors only during final testing, then have to restart the entire activation.
Beyond basic task chaining, smart automation can run parallel provisioning tracks for network, security, and application layers, then converge them only when all pass their checkpoints. If one track stalls, the workflow notifies the right team with exact context instead of waiting for a scheduled review, keeping overall turn-up time predictable even under variable load.
Vendor-Neutral Hooks for Billing and Provisioning
Vendor-neutral hooks for billing and provisioning let you integrate payment and service activation workflows without tying your core logic to a specific gateway or telecom stack. Instead of hard-coding calls to a particular API, you expose a set of well-defined events and callbacks that any compatible system can consume. This keeps the integration layer thin and makes it far easier to swap out a billing provider or provisioning engine later, because the contract remains stable even when the underlying implementation changes.
From a practical standpoint, these hooks typically take the form of webhooks or message queue subscriptions that fire on key lifecycle events, such as a new account signup, a subscription upgrade, or a failed payment retry. On the provisioning side, you might emit an event when a user is activated, suspended, or removed, leaving the actual resource creation to whichever connector is currently registered. The key is that your application never needs to know the internal quirks of Stripe, Chargebee, or a telco's OSS. It only speaks the neutral event schema, and adapters translate that into vendor-specific operations.
One often-overlooked benefit is how much easier this makes local testing and dry runs. Because the hooks are decoupled from concrete vendors, you can run a stub billing provider or a mock provisioning service that simply logs events and returns canned responses. This allows developers to exercise the full lifecycle without setting up real merchant accounts or provisioning sandboxes. Over time, the neutral interface also reduces onboarding friction for new partners, since they only need to implement a handful of documented hooks rather than rebuild your entire integration layer.
Monitoring Metrics That Map to Subscriber Experience
Tying network numbers to what subscribers actually feel requires moving beyond raw counters. Packet loss, latency spikes, and jitter often look harmless in aggregate but tell a different story when grouped by service type or geography. A single stalled video session can erase months of goodwill, so the right metrics focus on user-perceived events rather than interface utilization alone.
Instead of chasing every possible telemetry point, teams benefit from a short list of indicators that bend toward experience. Think mean opinion score for voice calls, buffering ratio for streaming, page load time for data sessions, and failed connection attempts during peak hours. Each one answers a simple question: did the subscriber get what they paid for in that moment?
The real differentiator comes from pairing these experience metrics with network context. When latency rises in a specific cell sector, correlation with signal quality and backhaul congestion points to the root cause quickly. That shift from monitoring infrastructure to monitoring the human at the edge changes how alarms are set, how capacity is planned, and ultimately how churn is prevented.
FAQ
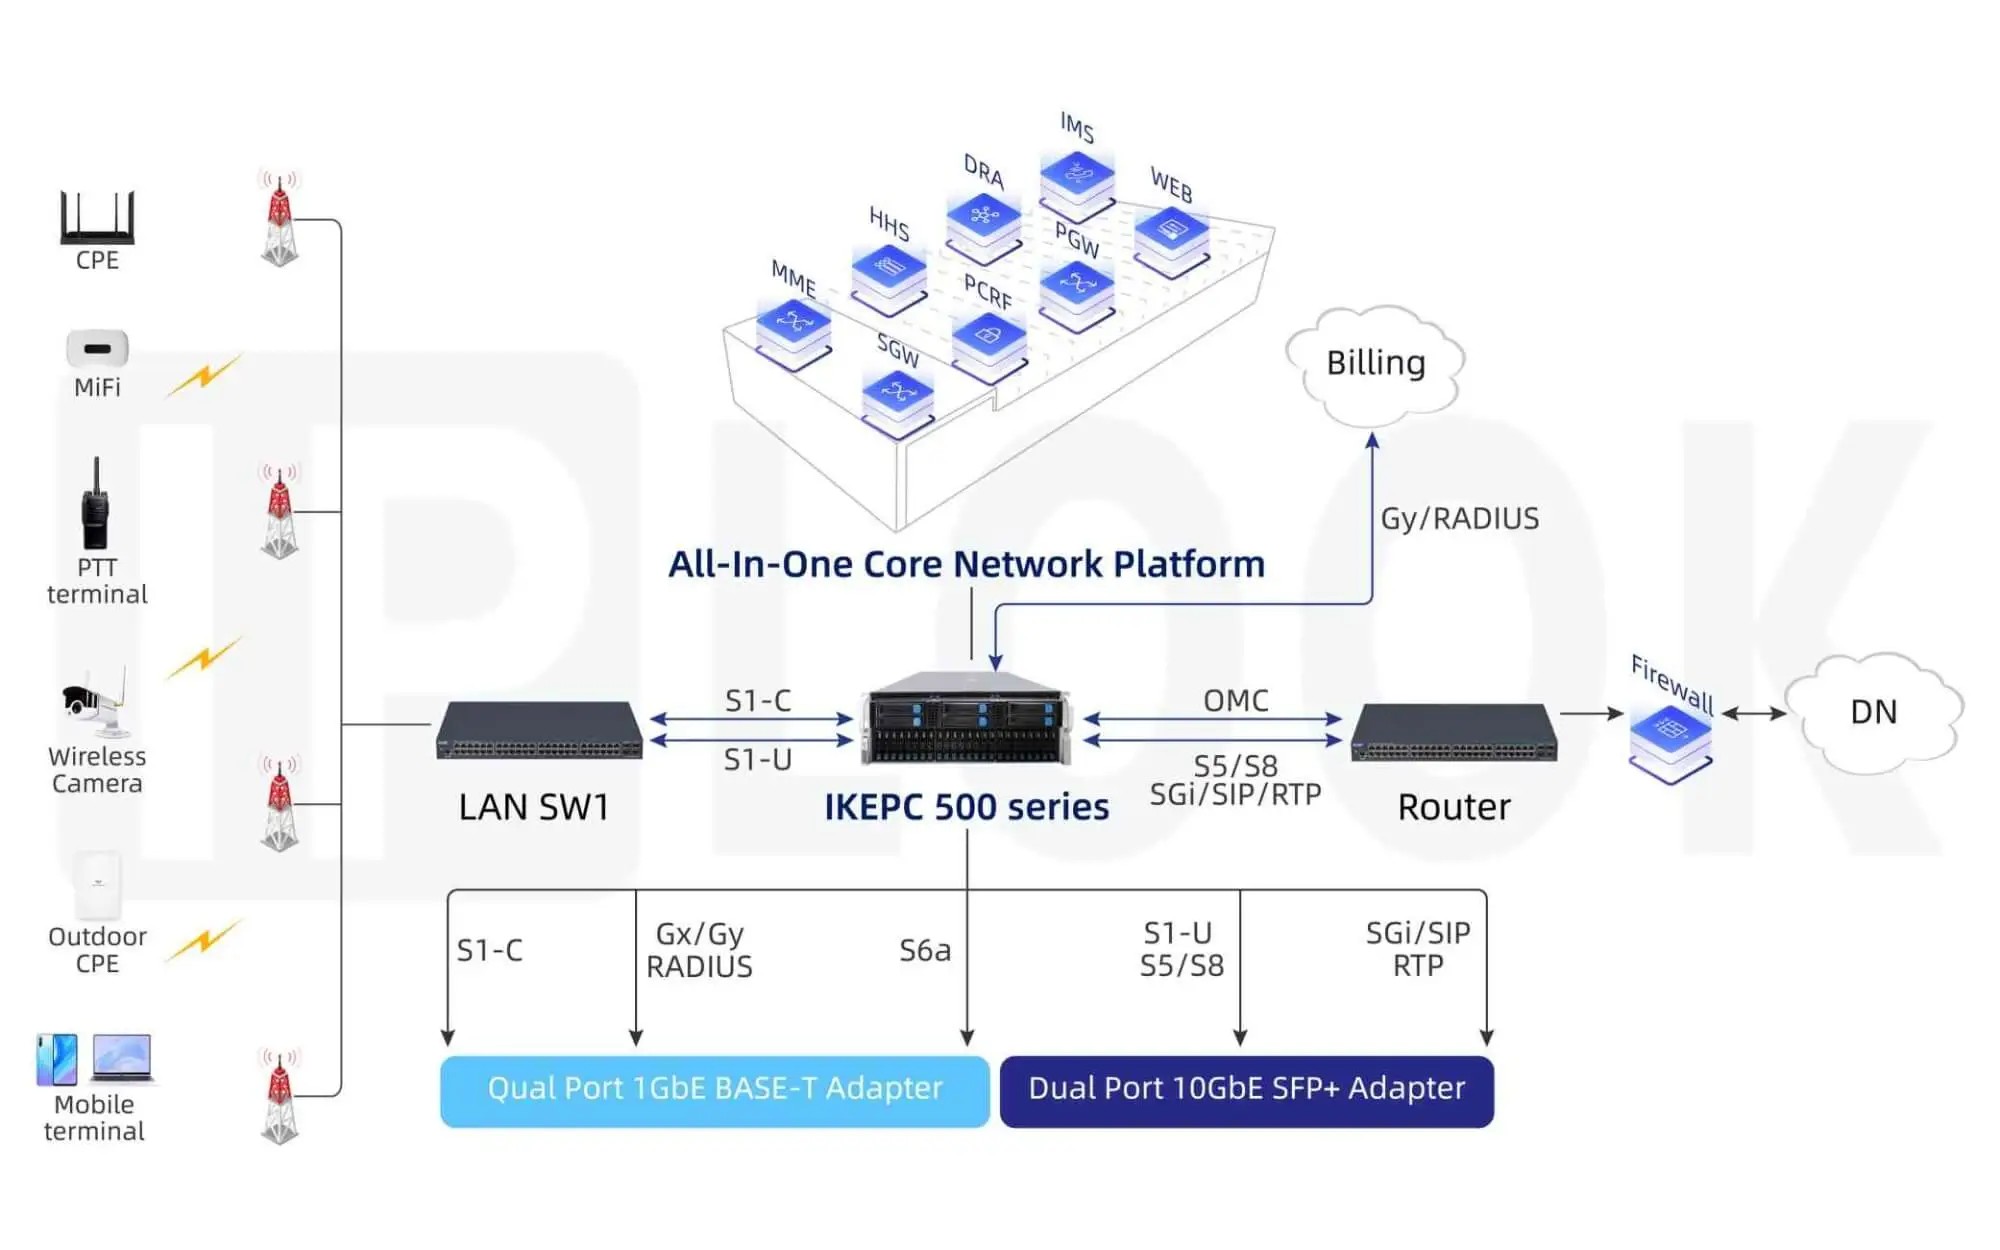
A white label IMS core lets you run the entire IMS stack under your own brand while the underlying software and infrastructure come from a third party. The key difference is that you're not forced into the vendor's service definitions, pricing templates, or customer-facing portals. You get full control over how subscribers are provisioned, which supplementary services are exposed, and how billing events are generated. In practice this means a regional operator can differentiate on service bundles and local numbering plans without having to maintain a full in-house IMS development team.
Start with a small, separate virtualized IMS instance that only handles new VoIP or VoLTE subscribers initially. Keep the existing TDM or legacy softswitch running for current customers, and route calls between the two through a standard SIP interconnect. This lets you validate call quality, number portability, and emergency call routing in a controlled way. Once the pilot group proves stable over several weeks, you can gradually migrate subscriber batches by moving their profiles from the HLR/HSS into the white label core's subscriber database.
Legal interception and emergency calling are the two that tend to surface late. Both require coordination with local regulatory bodies and often need physical or logical interfaces that aren't part of the basic IMS package. Beyond those, operators frequently miss online charging integration, especially for prepaid accounts, and policy control via PCRF/PCEF, which affects how QoS is applied for VoLTE. Another commonly overlooked item is voice mail retrieval routing and short-code dialing plans, which need explicit mapping in the new core.
Yes, but only if the platform supports true multi-tenancy rather than just virtual hosting on the same hardware. You need isolated network slices or virtual routing domains per tenant, separate subscriber data partitions, and dedicated media processing resources for high-priority tenants. Security isolation matters just as much as performance: one tenant should never see another tenant's signaling traces or be able to trigger resource exhaustion. Many operators achieve this by deploying per-tenant I-CSCF/S-CSCF instances that share only the HSS and charging gateways.
The most useful tests are end-to-end call scenarios that mirror actual subscriber behavior: mobile-originated and mobile-terminated VoLTE calls, mid-call handover from LTE to 3G with SRVCC, and roaming registration from partner networks. Load testing on the signaling plane matters more than raw media throughput, because IMS control nodes can fail under high CPS rates long before bandwidth saturates. Fault injection, like killing a SIP proxy or cutting a database link, shows whether the system fails over cleanly. Automating these scenarios as regression tests saves you from repeating the same manual checks after every software update.
The trick is to use network segmentation and role-based access controls from day one, so security doesn't depend on every engineer remembering to apply a manual setting. Encrypt signaling with IPsec or TLS where peers support it, and keep management interfaces on a separate out-of-band network. Regular patch cycles and configuration audits can be automated with scripts that compare running configs against a known baseline. Centralized logging and alerting then let the operations team spot abnormal SIP traffic or failed login attempts without having to log into every node individually.
Treat the IMS configuration as code. Store all node configs, S-CSCF profiles, application server triggers, routing rules, in a version control system, and promote changes through a CI/CD pipeline that runs automated smoke tests before touching production. Weekly or monthly audits compare the live network state against the repository baseline, flagging any manual overrides. When you do need to change a parameter, apply it to a small canary group of subscribers first, watch key metrics like registration success rate and call setup time, then roll out to the rest.
Conclusion
Deploying a white-label IMS core demands more than assembling standard network functions. The architecture must keep multiple tenants from interfering with one another; this means strict separation of signaling and media paths, per-tenant name spacing in the control plane, and resource quotas that prevent one customer's traffic storm from degrading another's service. On the containerization front, the temptation to lift-and-shift VNFs into Kubernetes often backfires under peak load. Instead, sizing CPU and memory requests based on real call model forecasts, pinning stateful components like the HSS or S-CSCF to dedicated nodes, and testing failover with actual subscriber sessions are what hold the stack together. Security should follow a similar restraint: encrypt east-west traffic with mutual TLS, enforce least-privilege access to the orchestration layer, and drop unnecessary ports rather than layering on extra firewalls that add latency without real protection.
Automation is most valuable when it cuts service turn-up time, so workflows should focus on reusable network function descriptors, templated Diameter routing tables, and CI/CD pipelines that validate configuration changes before hitting production. Vendor neutrality matters here because billing and provisioning hooks must not become a recurring integration tax. Exposing standard REST or Diameter interfaces, and streaming call detail records through a neutral event bus, keeps an operator free to swap IMS components without rewriting the business support stack. Finally, monitoring should reflect what subscribers actually experience: setup success rate, post-dial delay, one-way audio incidence, and registration latency are far more actionable than raw CPU graphs. Tying these metrics to per-tenant dashboards lets operations teams spot degradation early and fix issues before they become customer churn.
Contact Us
Contact Person: Shimmy
Email: [email protected]
Tel/WhatsApp: 85253392231
Website: https://www.iplook.com